Performance Lab
- Work on
lnxsrv15.seas.ucla.edu(connect to it directly, see Getting Started)- Grading server
lnxsrv08: do not run the lab there, other students' grades depend on it being quiet- Download / scoreboard
- lnxsrv08.seas.ucla.edu:18213 (on the UCLA VPN)
- Lab TA
- Yuyue Wang
Before you start
- This is an individual assignment: all code must be your own. You may discuss optimization ideas with other students; if you do, list them as collaborators at the top of kernels.c.
- After you untar the lab download, keep the folder named “target-NUMBER”.
- kernels.c must not contain the text
asm,#pragmaorallocanywhere, even in comments; the server rejects it automatically (see Rules).
Introduction
In this lab you will optimize four simple “kernels” using the techniques from class, to make them faster and more energy efficient. The kernels are tested in six cases: one each for Dot, Transpose and MatVec, and three problem sizes for Stencil.
We approximate energy efficiency by the amount of data moved across the levels of the memory hierarchy, so try to hit in the L1 cache as much as possible. The cache and memory optimizations from class matter most here.
Your grade depends on one number, the energy-delay improvement: how much faster your code is than the original, times how much less memory energy it uses (each a geometric mean over the six tests). The unoptimized code scores about 1.3, which is 0 points; about 125 earns 100. The details are under Grading and Rules.
Getting Started
Use lnxsrv15.seas.ucla.edu to edit and run your files (in VS Code Remote-SSH, add the host <yourusername>@lnxsrv15.seas.ucla.edu). Note that cs33.seas.ucla.edu may send you to lnxsrv08, the grading server, so please connect to lnxsrv15 directly for this lab. The first time you connect you will be asked to confirm the host fingerprint; type yes.
Go to the lab website in your browser (you need to be on the UCLA VPN). Click the “Request Lab” button, enter the requested information and you’ll get a tarball. Then
upload it to lnxsrv15 with scp or a file transfer tool such as CyberDuck. With scp, run this on your own computer:
scp <yourlocalfile> <yourusername>@lnxsrv15.seas.ucla.edu:~/<yourdir>
Alternatively, you can log into lnxsrv15 and download it with this command (substituting YOURUID and YOUREMAIL):
curl -X POST -d "uid=YOURUID&email=YOUREMAIL" -H "Content-Type: application/x-www-form-urlencoded" -O --remote-header-name "http://lnxsrv08.seas.ucla.edu:18213/get-tar-file"
If you are not already logged in, log onto lnxsrv15 with a terminal or your editor (VS Code, etc.). Go to the directory with the tarball, untar it, and enter the folder. Replace YOURNUMBER with the number assigned to your tarball, and keep the folder name as is.
ssh <yourusername>@lnxsrv15.seas.ucla.edu
tar -xzf target-YOURNUMBER.tar.gz
cd target-YOURNUMBER
Optimize the code in kernels.c. To check its correctness and performance, compile it and run all the tests:
make
./perflab
Make sure to run make (not make perflab): there’s another binary called plain that needs to be compiled as well.
You can also run a single test by passing its number (e.g. test 2):
./perflab -i 2
Kernel tests and parameters:
| Test | Kernel | Ni | Nj | Nk | S |
|---|---|---|---|---|---|
| 0 | Dot | 2048, 16387 | - | - | - |
| 1 | Transpose | 10000 | 10000 | - | - |
| 2 | MatVec | 1000 | 1000 | - | - |
| 3 | Stencil | 128 | 128 | 128 | 8 |
| 4 | Stencil | 64 | 64 | 64 | 20 |
| 5 | Stencil | 4 | 4 | 1048576 | 2 |
Your local run on lnxsrv15 checks correctness, measures time, reads the hardware performance counters, and shows the
cache statistics and an estimated grade, just like the grading server.
Local timing on lnxsrv15 is only a guide – the machine is shared, so your local speedups may look lower than what the grading server measures.
Interpreting the output
Each run prints one row of statistics per test, then your Energy-Delay Improvement and Grade. Even the unoptimized code gets an energy-delay improvement of about 1.3 on the grading server, so the grade starts counting from 1.3.
Example output and what each column means
Here is the output of the original (unoptimized) code from the grading server:
| Test | Time | Instructions | Accesses per 1000 elements | Energy | vs. original | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| T# | Kernel | Size | Time (ms) | CPE | #Ins PE | #VecIns PE | L1 | L2 | L3 | MEM | MemEn (J) | Speedup | Energyup |
| 0 | Dot | 16387 | 899.857 | N/A | 2.521 | 0.125 | 252.5 | 67.3 | 0.1 | 0.036 | 0.053019 | 1.0 | 1.0 |
| 1 | Transp. | 10000 × 10000 | 366.528 | 7.33 | 25.910 | 0.000 | 6031.0 | 1056.9 | 23.6 | 7.486 | 0.049392 | 1.6 | 0.9 |
| 2 | MatVec. | 1000 × 1000 | 172.057 | 43.01 | 54.102 | 0.000 | 11014.3 | 1419.6 | 458.7 | 10.633 | 0.008227 | 2.5 | 1.0 |
| 3 | Stencil | 128 × 128 × 128, S=8 | 4327.065 | 8.06 | 16.432 | 0.000 | 5857.7 | 28.8 | 5.7 | 3.158 | 0.354565 | 1.0 | 1.0 |
| 4 | Stencil | 64 × 64 × 64, S=20 | 8236.750 | 7.86 | 14.892 | 0.000 | 5309.2 | 2780.8 | 3.3 | 1.439 | 1.173541 | 1.0 | 1.0 |
| 5 | Stencil | 4 × 4 × 1048576, S=2 | 640.698 | 9.55 | 33.126 | 0.000 | 12333.5 | 155.2 | 16.4 | 9.251 | 0.098370 | 1.3 | 1.0 |
Show the same output as it appears in your terminal
T#  Kernel |      Ni    Nj      Nk  S |   Time(ms)    CPE  #Ins PE  #VecInsPE |  L1 KPE  L2 KPE  L3 KPE MEM KPE MemEn(j) | Speedup Energyup
 0     Dot |   16387     -       -  - |    899.857    N/A    2.521      0.125 |   252.5    67.3     0.1   0.036 0.053019 |     1.0      1.0
 1 Transp. |   10000 10000       -  - |    366.528   7.33   25.910      0.000 |  6031.0  1056.9    23.6   7.486 0.049392 |     1.6      0.9
 2 MatVec. |    1000  1000       -  - |    172.057  43.01   54.102      0.000 | 11014.3  1419.6   458.7  10.633 0.008227 |     2.5      1.0
 3 Stencil |     128   128     128  8 |   4327.065   8.06   16.432      0.000 |  5857.7    28.8     5.7   3.158 0.354565 |     1.0      1.0
 4 Stencil |      64    64      64 20 |   8236.750   7.86   14.892      0.000 |  5309.2  2780.8     3.3   1.439 1.173541 |     1.0      1.0
 5 Stencil |       4     4 1048576  2 |    640.698   9.55   33.126      0.000 | 12333.5   155.2    16.4   9.251 0.098370 |     1.3      1.0
Geomean Speedup: 1.31
Geomean Energyup: 0.98
Energy-Delay Improvement: 1.29
Grade: 0.0
What the columns mean:
| Column | Meaning |
|---|---|
| Size | Ni × Nj × Nk and stencil size S (for Dot, the vector length) |
| Time (ms) | Execution time in milliseconds |
| CPE | Cycles Per Element (estimated from the time) |
| #Ins PE | Instructions Per Element |
| #VecIns PE | 256-bit SIMD/Vector floating-point Instructions Per Element |
| L1 / L2 / L3 / MEM | Number of L1 / L2 / L3 / memory accesses per one thousand elements (the “KPE” columns in the terminal) |
| MemEn (J) | Memory energy in joules (see Scoring below) |
| Speedup | Speedup of your program compared to the original code |
| Energyup | Energy improvement of your program compared to the original code |
To be graded, submit your work to the grading server:
make submit
The server compiles and runs your code on lnxsrv08 and streams the result back to you. While you wait, it shows your place in the queue.
A full run of the unoptimized code takes about a minute; faster code finishes sooner.
Submission limits
- You can have one submission at a time queued or being graded. If you submit again before it finishes, the server replies “You already have a submission queued or being graded.”
- You can submit at most 5 times per hour (a rolling 60-minute window). Submissions that fail to compile or are rejected still count. When you hit the limit, the server tells you how many seconds to wait.
- As the deadline approaches, the queue will get long. Start early!
Scoreboard comments, grades and backups
- If you want a comment to be shown on the scoreboard, write it in comment.txt and keep it short. A super long string will be rejected by the server.
- You can submit multiple times; your grade is your best score on the scoreboard, unless we find that you didn’t follow the rules.
- Save your progress often and keep backups of previous versions of your code, for example with Git.
Kernels
Kernel numbers match the test numbers (T#) in the output.
Kernel #0: Dot product (warm up)
Compute the dot product of two float vectors a and b of length n, and write it to *result:
void compute_dot(int n, const float a[n], const float b[n], float *result);
The inputs are read-only, result does not overlap them, and every call must overwrite *result
(including 0 for n = 0). The test uses lengths 2048 and 16387. Remembering answers from previous
calls is not allowed.
Hints
- Look at the loop-carried dependence on
sum: every addition has to wait for the previous one. Can you break that chain? - Don’t worry about vector intrinsics; plain C is enough.
Kernel #1: 2D Transpose
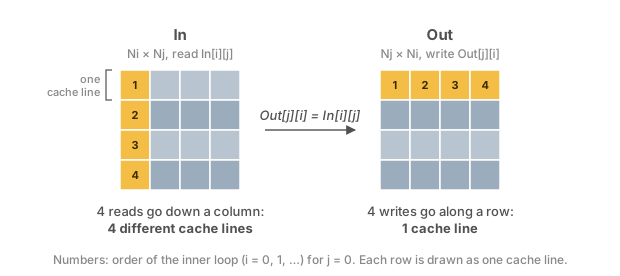
In 2D transpose, we take a 2D input matrix (Ni by Nj), and swap its rows and columns to create a 2D output matrix (Nj by Ni).
We can define the transpose mathematically as follows:
\[Out_{i,j} = In_{j,i}\]The given code’s inner loop walks down a column of In and along a row of Out:
Hints
- Think about the cache access pattern – it seems like we get bad spatial locality on either the In or Out array.
- Can we use tiling to help?
- Don’t worry about vector instructions for this one.
Kernel #2: Complex Matrix-Vector Multiplication
Here we are doing a matrix-vector multiplication (similar to the one in class) but with complex numbers.
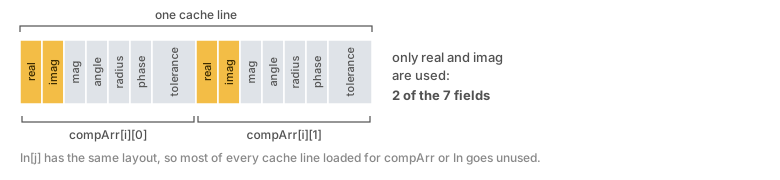
\[\displaystyle Out_{i} = \displaystyle \sum_{j=0}^{N_{j}-1} In_{j} \times compArr_{i,j}\]Each element of compArr and In is a Complex struct (see kernels.h), stored in memory like this:
Hints
- The complex values are defined with a struct (see
kernels.h). Think about the access pattern that is created when multiplying the values due to this struct. compArris a global variable that does not change. Can you think of a way to reformat it into a new data structure to avoid the nasty access pattern?- Specifically you can use the
init()function (not timed) to preprocesscompArr, and feel free to add global variables.
Kernels #3–5: 3D Stencil
Stencil algorithms “apply” a stencil (sometimes called a filter) to an input array to produce an output array. Stencil methods are quite common in image processing and computer simulations.
This stencil algorithm involves 3 arrays:
- “Input”: This is a large 3D array of input floating point values, with dimension sizes Ni, Nj, Nk. It has some padding in each dimension, based on the size of the Stencil array.
- “Stencil”: This is a smaller array of floating point values, with size S in all dimensions, which gets shifted over the input.
- “Output”: This is the same size as the input array, but without padding.
Below is a visualization of the three arrays involved:
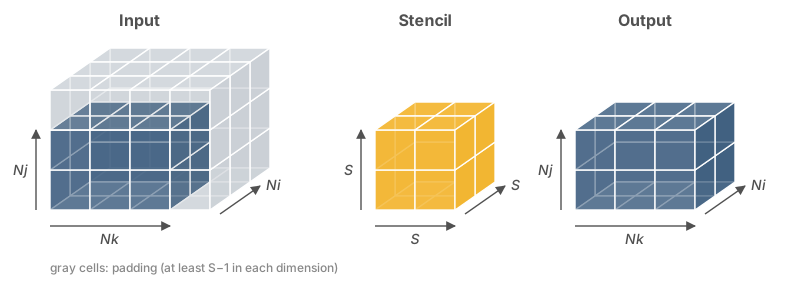
For each output cell, place the stencil over the corresponding region of Input, take the dot product of the Stencil values and the Input values beneath them, and write the result to that cell of Output.
In this lab, we’ll define the 3D stencil for each cell of the output as follows:
\[\displaystyle Out_{i,j,k} = \displaystyle \sum_{x=0}^{S-1} \sum_{y=0}^{S-1} \sum_{z=0}^{S-1} In_{i + x,j +y, k + z} \times Stencil_{x,y,z}\]The illustration below shows the computation for the first three output cells.
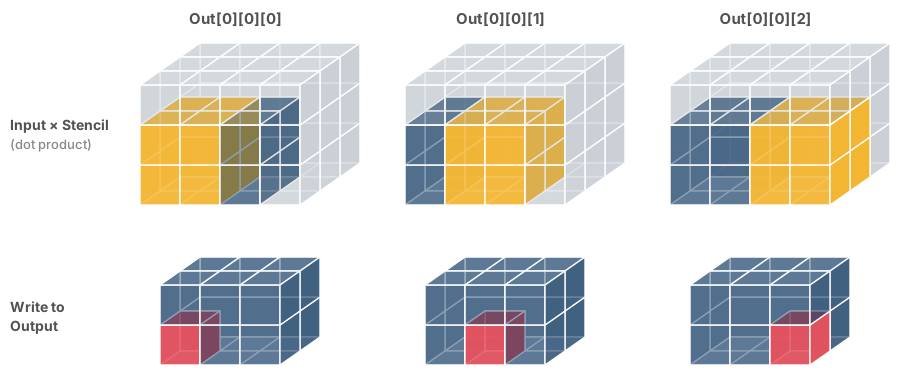
Neighboring output cells reuse much of the same input data, and every output cell uses all the stencil values. In the illustration, the second step (for $Output_{0,0,1}$) reuses half of the input cells from the first step.
Hints
- Create a specialized version for each problem size listed under “Kernel tests and parameters” in Getting Started. You may assume these sizes don’t change. When the dimensions are constants, the compiler can generate more efficient code.
- There is so much reuse that tiling is not so important here. For workload 5, however, there is an opportunity to tile.
- Loop ordering matters a lot: order the loops to get good temporal and spatial locality.
- It will help you play with the loop ordering if you zero out the Output array in a separate loop.
- GCC can vectorize this code. Make sure the statistics show that you are executing vector instructions – if not, your inner loop might not be chosen well to get contiguous access.
Optimization Strategy
Do these first
- Inline all the functions! This reduces function call overhead, and enables the compiler to reason about the program region.
- Create a special version of each kernel that is specific to the matrix dimensions in each test case. This has two benefits: the compiler can create simpler code because it knows what the matrix dimensions are, and you can also optimize for each kernel differently. E.g. in the compute_stencil function, check the input arguments to see if they match one of the test cases, then call a version specific to that test case.
- Try different loop orderings. Think about which ordering gives you the best spatial locality. Spatial locality is good for cache performance and the compiler will naturally vectorize loops with good locality.
- You can also try adding the “restrict” keyword in the first (outer) dimension of your array – this tells the compiler that the corresponding memory arrays don’t overlap, and could make the compiler’s job easier. This helps a little on some of the stencil cases.
- Syntax:
func(float a[restrict N][N][N] ...)
- Syntax:
General advice
- After each change, check the stats (#instructions, cache accesses, etc.) to understand what worked and why. For example, tiling should improve locality in L1 and reduce L2 accesses; if L2 accesses don’t drop, check your tiling code and tile size.
- You’re going to see some performance variation between runs. This is unavoidable – we are running on a real machine where OS-level events, as well as other programs, can affect your performance.
- Simpler code is often better for the compiler. If a change doesn’t help, roll it back and keep the simpler version. For example, manual unrolling can make things worse because the code gets more complex.
- Sometimes a recommended optimization (i.e. in the hints section) may slightly lower the performance for a particular case. That can come from an interaction with the compiler or from run-to-run variation. Keep trying the other suggestions, and tune parameters such as the tile size.
- Start early. Near the deadline, the submission queue gets much longer.
Optional, if you want to dig deeper
- Use tiling to improve temporal locality in the stencil, so you don’t walk down a very long dimension without reuse in the cache. To pick a tile size, compute the size of the data the inner loops touch and keep it below the size of the cache you are targeting.
- To see whether GCC vectorized a loop, add
-fopt-info-vec-allwhen compiling kernels.c (a comment in the Makefile shows where; this only affects your local build, not grading). Look for your loop’s line number in the report. Sometimes GCC vectorizes an outer loop. - Read the generated assembly of kernels.o (in the build/ folder) with objdump or gdb to see which source changes help the compiler. Code at
-O3can be hard to read.
CPU Microarchitecture Parameters
The grading server (lnxsrv08) and lnxsrv15 both run on an Intel(R) Xeon(R) Silver 4116 CPU @ 2.10GHz (Skylake-SP).
It shouldn’t be necessary to know the specific CPU properties to get a good grade; however, it could be useful for some advanced optimizations, and also just for understanding your results in general.
Compute
Your code is compiled with GCC 16.2 and -O3 -mavx, so the compiler can use 256-bit
AVX instructions:
a single AVX instruction can do eight float operations.
Cache
The cache line size is 64 bytes. Here’s the size of the three levels of cache:
| Level | Size | Shared? |
|---|---|---|
| L1d | 32 KiB | private to each core |
| L2 | 1 MiB | private to each core |
| L3 | 16.5 MiB | shared by all cores of the machine |
Grading and Rules
Scoring
For performance, we measure execution time. For energy efficiency, we approximate it with “memory energy”:
the grading server runs your program under Linux perf and reads the CPU’s hardware performance counters
for the number of accesses to L1, L2, L3 and memory, then weights each access by a (somewhat arbitrary) constant:
For each of the six tests, your Speedup is the original code’s time divided by yours, and your Energyup is the original code’s memory energy divided by yours. We take the geometric mean of each across the six tests and multiply them to get the “energy-delay improvement”:
\[EnergyDelayImprovement = geomean(Speedup) \times geomean(Energyup)\]Your grade is computed from the energy-delay improvement using the cutoffs below, interpolating linearly in between:
| Energy-Delay Improvement | Grade | Reference point |
|---|---|---|
| 1.3 or less | 0 | about where the unoptimized code is |
| 3.7 | 60 | |
| 7.3 | 80 | C reference solution |
| 29 | 90 | B reference solution |
| 125 | 100 | A reference solution |
| 200 or more | 105 | +5% extra credit cap |
For reference, the TA solution achieves an energy-delay improvement of about 125, and it is possible to do better.
Rules
No assembly, no #pragma, no memory allocation
The server enforces this by rejecting any kernels.c that contains the text asm, #pragma or alloc anywhere, including in comments and variable names (e.g. chasm, reallocate). Avoid those letter sequences entirely.
- Put all your code in kernels.c. The grading server ignores changes to any other file, including the Makefile. Do not rename any files.
- No external libraries in kernels.c (your own functions are fine). This also means no threads and no forking.
- Do not attack or tamper with the grading server.